Blog Detail

Insights, stories, and updates from the world of technology and innovation.

Blog Featured Image

RAG Beyond Vector Search: Hybrid Retrieval, Reranking and Context Optimisation

Published on Sep 1 hour ago · By FlipCode Team


Most teams building Retrieval-Augmented Generation (RAG) systems start the same way: embed your documents, store them in a vector database, and let cosine similarity do the rest. It works in a demo — clean questions, small corpus, forgiving evaluation. Then it hits production traffic, and the cracks show: exact-match queries return nothing useful, semantically "close" chunks turn out to be contextually wrong, and the context window fills up with three near-identical paragraphs while the one fact the model actually needed never made the cut.

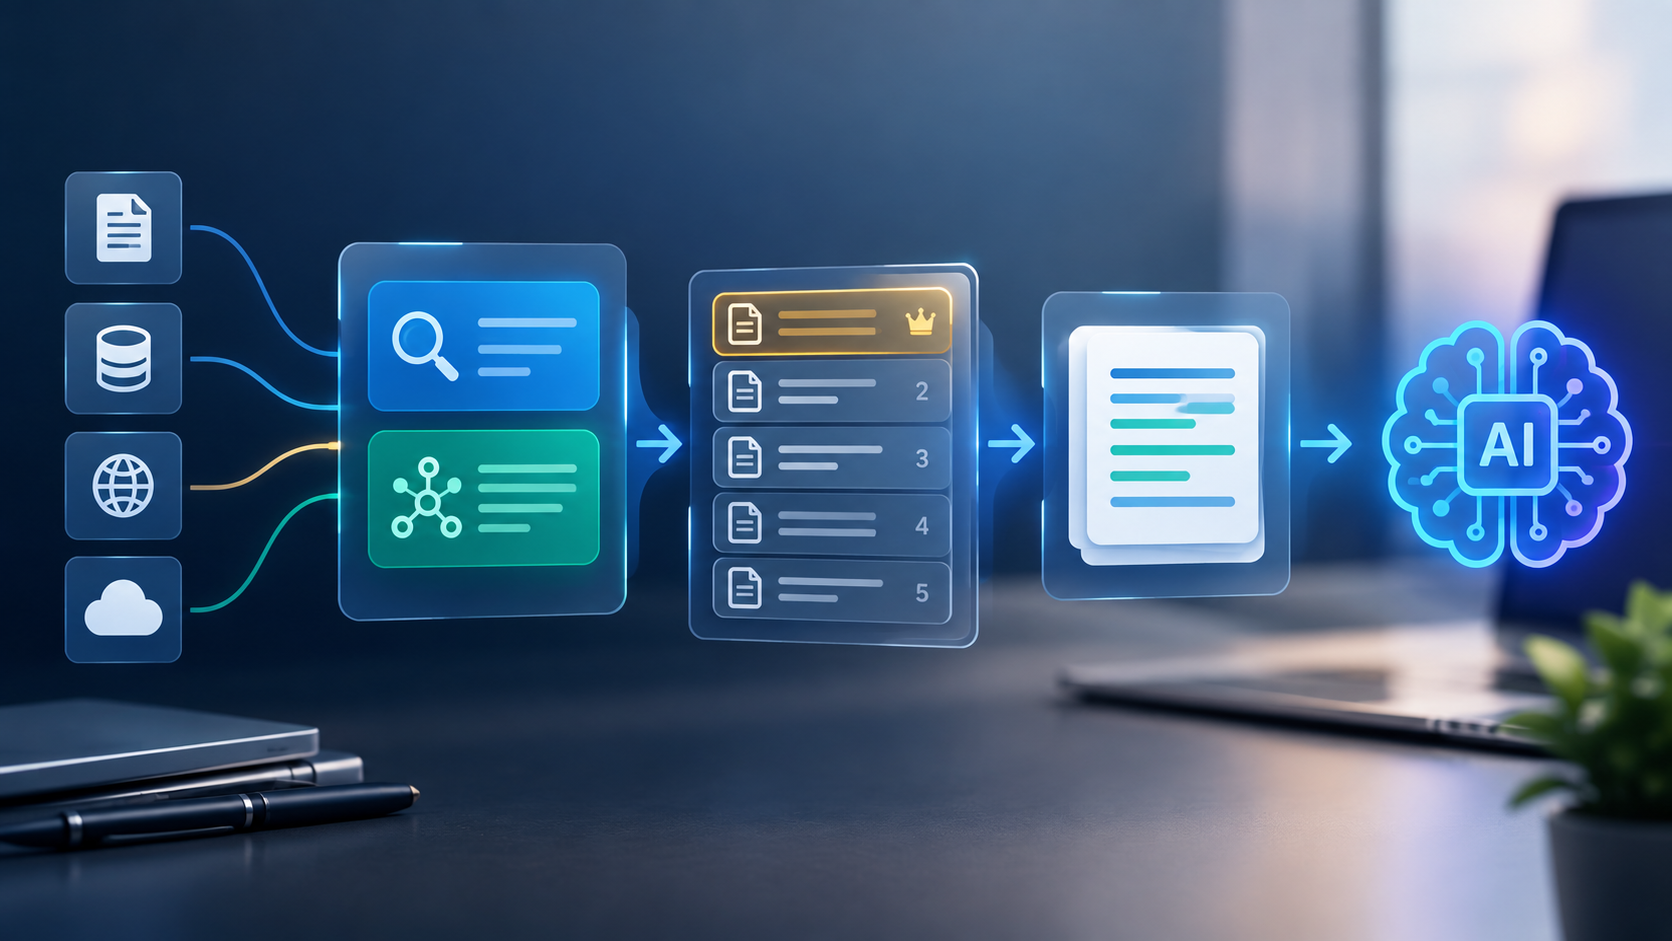
The fix isn't a bigger embedding model. It's a better retrieval architecture. This post covers the techniques that separate prototype RAG from production-grade RAG: hybrid retrieval, reranking, context optimisation, and the supporting layers — query transformation and evaluation — that make the whole pipeline trustworthy. This is the architecture Flipcode Solutions reaches for when a client's RAG system needs to hold up under real usage, not just a demo.

Why Vector Search Alone Falls Short

Dense vector search is excellent at capturing semantic similarity, but it has predictable, well-documented blind spots:

  • Exact-match failures: Product codes, error IDs, legal clause numbers, ticket numbers, and proper nouns often get buried because embeddings prioritize meaning over literal tokens. A query for "error E-4021" may retrieve documents about "connection errors" in general rather than the specific code.
  • Domain drift: Off-the-shelf embedding models trained on general web text underperform on specialized vocabulary — legal, medical, financial, or internal jargon that the model has rarely or never seen in training.
  • Semantic false positives: Two chunks can be neighbors in embedding space while being contextually irrelevant to the query's actual intent. "How do I cancel my subscription" and "how do I upgrade my subscription" often sit close together in vector space despite being opposite intents.
  • No notion of importance: Vector search ranks by distance, not by relevance to the specific question being asked, and it has no mechanism for weighing recency, authority, or specificity.
  • Chunking artifacts: A chunk that scores well on similarity might be missing the sentence right before or after it that actually resolves the query — a symptom of retrieval architecture, not the embedding model itself.

These gaps are exactly why production RAG systems increasingly combine multiple retrieval signals rather than relying on embeddings alone.

Query Transformation: Fixing the Problem Before Retrieval Even Starts

Before touching retrieval strategy, it's worth acknowledging that a large share of RAG failures start with the query itself. Users ask vague, underspecified, or multi-part questions, and feeding that raw text directly into a retriever often produces mediocre results regardless of how good the retrieval stack is downstream.

Common query transformation techniques:

  • Query rewriting: An LLM rephrases the user's query into a more retrieval-friendly form, expanding abbreviations, resolving pronouns from conversation history, and clarifying intent.
  • Query expansion: Generating multiple paraphrased versions of the query (e.g., HyDE — Hypothetical Document Embeddings — where an LLM writes a hypothetical answer and that answer's embedding is used for retrieval instead of the raw query).
  • Query decomposition: Splitting a multi-part question ("Compare X and Y, then explain the pricing implications") into sub-queries that are retrieved independently and reassembled.
  • Routing: Classifying the query type first (factual lookup vs. summarization vs. comparison) and sending it to a retrieval strategy tuned for that type.

This step is cheap relative to what it saves downstream — a well-formed query makes both hybrid retrieval and reranking meaningfully more effective.

Hybrid Retrieval: Combining Sparse and Dense Search

Hybrid retrieval fuses two complementary approaches:

  • Dense retrieval (vector embeddings) — captures semantic meaning, paraphrasing, and conceptual similarity.
  • Sparse retrieval (BM25 or similar keyword-based methods) — captures exact terms, acronyms, and rare tokens that embeddings tend to smooth over.

How It Works in Practice

  1. Run the (possibly transformed) query through both a vector index and a keyword index (e.g., Elasticsearch/OpenSearch BM25, or a library like rank_bm25).
  2. Retrieve the top-N candidates from each — typically 20–50 per system.
  3. Merge and normalize scores. The most common approach is Reciprocal Rank Fusion (RRF), which combines rankings without needing score calibration between the two systems. Dense cosine scores and BM25 scores live on entirely different scales, so naive score averaging doesn't work well.

RRF score:

RRF_score(doc) = Σ 1 / (k + rank_i(doc))

Where rank_i(doc) is the document's rank in retrieval system i, and k is a small constant (typically 60) that dampens the influence of very high ranks so no single system dominates the fused ranking.

Weighted Hybrid Variants

Some systems use a weighted linear combination instead of RRF:

score = α · dense_score + (1 − α) · sparse_score

With α tuned per domain. This requires normalizing both score distributions (e.g., min-max scaling) and tends to need more manual tuning than RRF, but can outperform it once tuned for a specific corpus.

When Hybrid Retrieval Matters Most

  • Technical documentation with SKUs, function names, or error codes
  • Legal and compliance corpora with specific clause references
  • Customer support knowledge bases mixing casual phrasing with precise terminology
  • Multilingual corpora where embedding quality varies by language but keyword matching remains stable

Most production-grade vector databases (Weaviate, Qdrant, Pinecone, Elasticsearch, Vespa) now support hybrid search natively, so this is often a configuration change rather than a rebuild.

Reranking: A Second, Smarter Pass

Hybrid retrieval gets you a better candidate pool — but the initial ranking still relies on relatively cheap similarity metrics computed independently for query and document. Reranking adds a second stage: a more expensive but far more accurate model that re-scores the top 20–100 candidates before final context selection.

Why Rerankers Outperform First-Stage Retrieval

First-stage retrieval (dense or sparse) scores query and document independently, then compares vectors or term overlap. Cross-encoder rerankers, by contrast, feed the query and document together into a transformer, letting the model directly attend to how the two relate token-by-token.

This joint encoding is computationally heavier — which is why it's applied only to a shortlist, not the full corpus — but it produces meaningfully better relevance judgments, often closing gaps that no amount of embedding fine-tuning fixes.

Common Reranking Approaches

Method Description Trade-off
Cross-encoder rerankers
(e.g., Cohere Rerank, BGE-reranker, Jina Reranker)
Jointly encode query + document and output a relevance score. High accuracy, higher latency, one forward pass per candidate.
LLM-based reranking Prompt an LLM to score or reorder candidates, optionally with chain-of-thought. Flexible and explainable, but costly and slow at scale.
ColBERT-style late interaction Token-level similarity between query and document embeddings. Balances speed and accuracy; more infrastructure complexity.
Learning-to-rank (LTR) models Classical ML models (e.g., LightGBM) trained on relevance features. Fast and interpretable, but needs labeled training data.

Practical Guidance

  • Rerank the top 20–50 candidates from hybrid retrieval, not the full result set — reranking cost scales linearly with candidate count.
  • Reranking typically adds 100–300ms latency for cross-encoders; budget for it in latency-sensitive applications like live chat.
  • A well-tuned reranker often improves answer quality more than swapping embedding models, and it's usually cheaper to iterate on than retraining or re-embedding an entire corpus.
  • If latency is critical, consider a lightweight reranker (distilled cross-encoder) or apply reranking only when first-stage retrieval confidence is low.

Context Optimisation: What Actually Goes Into the Prompt

Even with great retrieval and reranking, dumping the top-K chunks straight into the context window is a mistake. Context optimisation is about curating what the LLM actually sees, in what order, and in what form.

Key Techniques

  • Deduplication: Near-duplicate chunks from overlapping document sections (common with sliding-window chunking) waste tokens and dilute signal without adding new information.
  • Diversity-aware selection (MMR): Maximal Marginal Relevance balances relevance against redundancy, so retrieved chunks cover different aspects of the answer rather than repeating the same point from slightly different phrasings.
  • Chunk compression / summarization: For long chunks, an LLM or extractive summarizer can trim content to just the sentences relevant to the query before insertion — especially valuable when chunk size is large relative to the actual answer-bearing content.
  • Context ordering: Placing the most relevant chunks near the beginning and end of the context window helps mitigate the "lost in the middle" effect observed in long-context LLMs, where information buried in the middle of a long prompt is recalled less reliably than information at the edges.
  • Dynamic context sizing: Not every query needs 10 chunks. Simple factual queries may need 2–3; complex synthesis queries may need more. Sizing context dynamically based on query complexity avoids both under- and over-stuffing the prompt.
  • Metadata injection: Attaching source, date, section headers, and confidence scores to each chunk helps the LLM ground its answer, cite sources accurately, and avoid presenting stale information as current.
  • Contextual compression at the chunk level: Some pipelines apply an LLM pass that strips irrelevant sentences from each retrieved chunk while preserving the relevant ones — tighter than full summarization but more targeted than raw truncation.

A Simple Context Assembly Pipeline

  1. Hybrid retrieve top 50 candidates
  2. Rerank to top 10–15
  3. Deduplicate near-identical chunks
  4. Apply MMR for diversity
  5. Compress oversized or noisy chunks
  6. Order by relevance (front-load and back-load high-relevance content)
  7. Inject into the prompt with source metadata

Evaluating the Pipeline: How to Know It's Actually Working

None of the above matters if you can't measure whether it's improving answers. Production RAG teams typically evaluate at two levels:

Retrieval-Level Metrics

Does the pipeline find the right chunks?

  • Recall@k: Does the correct chunk appear in the top k results?
  • MRR (Mean Reciprocal Rank): How high does the first correct result rank, on average?
  • NDCG: Accounts for graded relevance, not just binary correct/incorrect.

Generation-Level Metrics

Does the final answer hold up?

  • Faithfulness / groundedness: Is the answer actually supported by the retrieved context, or is the model hallucinating beyond it?
  • Answer relevance: Does the answer address what was actually asked?
  • Context precision/recall: Of the retrieved chunks, how many were actually used in the answer, and were any necessary chunks missing?

Frameworks like RAGAS, TruLens, or a custom labeled evaluation set (even 50–100 hand-labeled query/answer pairs) let you A/B test changes — a new reranker, a different chunking strategy, an added hybrid weight — against a baseline instead of guessing.

This is the step teams most often skip, and it's usually why "we tried reranking and it didn't help" turns out to mean "we never actually measured it."

Common Pitfalls Worth Naming

  • Over-chunking: Splitting documents too finely destroys context that spans sentence or paragraph boundaries, making even perfect retrieval return fragments that don't answer the question.
  • Ignoring chunk overlap tuning: Too little overlap loses boundary context; too much inflates the index and increases duplicate retrieval.
  • Treating reranking as a silver bullet: Reranking can only reorder what first-stage retrieval already found — if the right chunk never makes the candidate pool, no reranker recovers it.
  • Static top-k for every query: Fixed k values are a common default that underserves complex queries and wastes tokens on simple ones.
  • Skipping evaluation until something breaks: Without a baseline, it's nearly impossible to tell whether a pipeline change actually helped.

Putting It Together: A Production RAG Architecture


Query
  │
  ├── Query Rewriting / Expansion / Decomposition
  │
  ├── Sparse Retrieval (BM25) ──┐
  ├── Dense Retrieval (Vector) ─┼──> RRF Fusion ──> Top 50
  │
  ├── Cross-Encoder Reranker ──> Top 10–15 Candidates
  │
  ├── Dedup + MMR + Compression ──> Final Context Window
  │
  ├── LLM Answer Generation
  │
  └── Evaluation Loop (Recall@k, Faithfulness, Answer Relevance)
    

This layered approach costs more in latency and infrastructure than naive vector-only RAG, but it directly addresses the failure modes teams hit in production: missed exact matches, irrelevant chunks, context-window bloat, and — critically — the inability to know whether any of it is actually working.

Conclusion

Vector search is a strong starting point for RAG, but it's not the finish line. Query transformation cleans up what enters the pipeline. Hybrid retrieval closes the gap on exact-match queries. Reranking sharpens relevance beyond what embeddings alone can judge. Context optimisation ensures the LLM sees a clean, non-redundant, well-ordered set of evidence. And evaluation ties it all together, turning "we think this is better" into something you can actually prove.

Together, these layers are what separate a RAG demo from a RAG system that holds up under real usage.